After a model has read most of the internet, it can write almost anything. What it cannot know on its own is which answer a careful person would prefer. That judgement has to come from people.
This is the idea behind human feedback, and it is still the most reliable way to steer a model toward the behaviour you want.
Better is a judgement, not a fact#
Ask two experts which of two answers is better and you will often get the same pick for different reasons. One liked the structure. Another spotted a subtle error in the third line.
A model cannot derive that from raw text. It needs many examples where a person looked at two outputs and chose, ideally with a short reason.
How the comparison works#
The process is simple to describe and hard to do well.
- Show a reviewer a prompt and two or more model answers
- Ask them to rank the answers, using written guidelines
- Collect a short note on why, especially for close calls
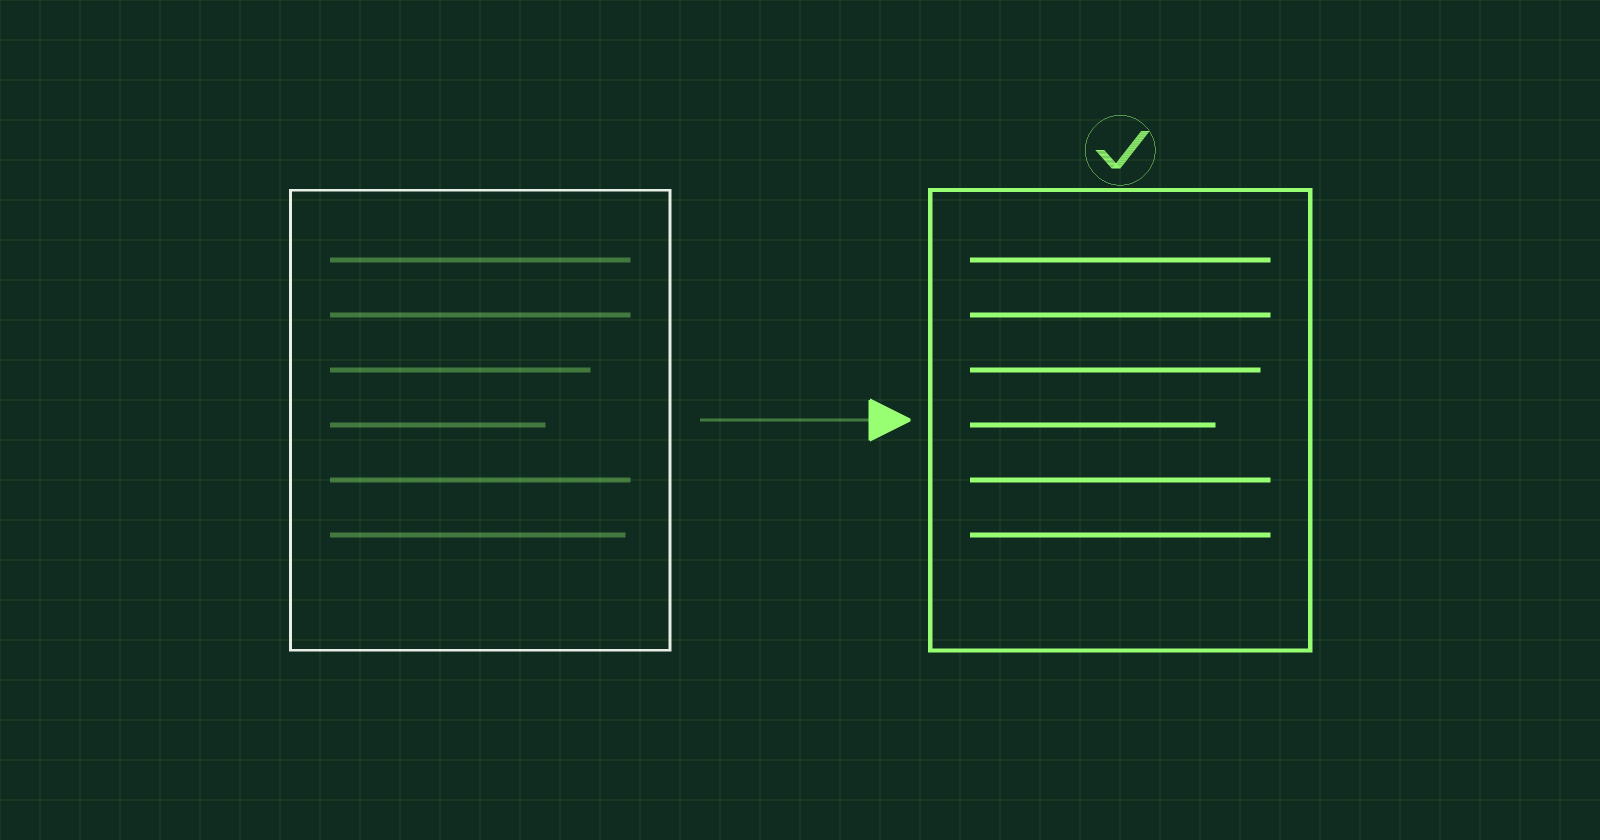
- Use the rankings as the training signal for fine-tuning
The quality of the guidelines and of the reviewers decides the quality of the result. A rushed comparison teaches the model to be confidently average.
Why domain experts change the outcome#
For general chat, a well-trained reviewer is enough. For code, medicine, law or finance, the person ranking must be able to tell a correct answer from a convincing one.
That is why we use vetted domain experts for high-value areas such as coding and data science. Their rankings carry information a generalist cannot add. See how this works in our human feedback service.
Keep the loop honest#
Two habits keep feedback useful:
- Measure agreement. If reviewers often disagree, the guidelines are unclear, not the reviewers
- Test on fresh cases. Check the tuned model on questions it never saw, with the same experts judging
Human feedback is not a replacement for good data or good evaluation. It is the part that tells the model what good looks like. Teams that treat it as a craft, with clear guidelines and real expertise, get models that behave the way their users expect.